Multicoin Cap2026-09-30 01:32:10Multicoin Capital backs Grass in a bet on real-time retrieval and machine intelligence data infrastructureMulticoin Capital said on Sept. 30 that it has invested in Grass through its hedge fund and venture fund, adding exposure to a DePIN project focused on internet data collection and retrieval infrastructure. Grass says it uses token incentives to aggregate unused residential bandwidth from more than 6 million contributors worldwide, creating a base layer for crawling and parsing public internet data. The network currently serves leading AI labs with model pretraining data and, according to the company, is already profitable. Official figures cited by Grass show $17 million in revenue for 2025 and another $17 million in the first half of 2026. The company expects full-year 2026 revenue from its training data business alone to reach $75 million. Grass also said it is expanding beyond training data into real-time contextual retrieval for inference workloads. As part of that push, it plans to launch a Contents API and a Search API aimed at meeting live data retrieval and web indexing needs for AI agent systems during runtime.80
MBZUAI2026-09-03 13:37:35MBZUAI institute unveils K2 Horizon open-source AI model seriesThe Institute of Foundation Models under MBZUAI has released the K2 Horizon family of open-source AI models, according to a Techub News item citing Crypto Briefing. The lineup includes six models, with parameter sizes ranging from 900 million to 375 billion. The release also includes the full training data. No additional details were provided in the brief. The update was published by Techub on Sept. 3, 2026.300
AI2026-08-03 02:03:42AI firms’ hunt for training data is fueling a global trade in old booksA TechFlowPost report, citing Fortune, The Washington Post, Decrypt and 404 Media, describes how demand for pre-2022 printed books is driving a cross-border supply chain built around bulk purchasing, destructive scanning and disposal of physical copies. The practice has drawn attention after court records in the Anthropic copyright case showed the company had downloaded more than 7 million books from pirate libraries in 2021 and 2022, then later launched a separate project to buy printed books in bulk, cut off their spines, scan them and destroy the originals. The report says a 2025 ruling by Judge Alsup split the legal questions in the Anthropic case: using books to train AI was treated as fair use, while downloading and permanently storing pirated copies was not. Anthropic later settled the class action for $1.5 billion, and the settlement received final court approval on July 20, 2026. According to the article, that line of reasoning has opened a clearer path for AI companies to acquire books legally, digitize them and keep only one digital copy. The piece also points to emerging infrastructure around that demand, including bulk procurement offers previously advertised by ISBNdb, as well as criticism from Elon Musk, who said rare books handled by his team should be preserved in a library and scanned non-destructively.3060
OpenAI2026-07-30 05:38:53Former OpenAI researcher Andrew Ho leaves to build an RL data startupAndrew Ho, a researcher involved in OpenAI’s biomedical AI evaluations including GeneBench and GeneBench-Pro, has left the company and says he is starting a new business focused on high-quality reinforcement learning, or RL, training datasets. His central argument is that the next constraint for large language models is no longer just more GPUs or bigger parameter counts, but access to data that can actually improve reasoning. Ho says today’s models still show limited generalization and what he calls “spiky capabilities,” performing well on select benchmarks while falling short in real work settings. He argues that many valuable tasks, from business decisions to medical judgment and scientific analysis, are too context-dependent to fit simple RL scoring setups. Ho also predicts that leading AI labs could spend more than $100 billion on high-quality training data in the coming years. His new company will start with datasets for biology and statistical reasoning, including long-horizon scientific reasoning tasks, before expanding into chemistry, materials science, healthcare, and white-collar work.6680
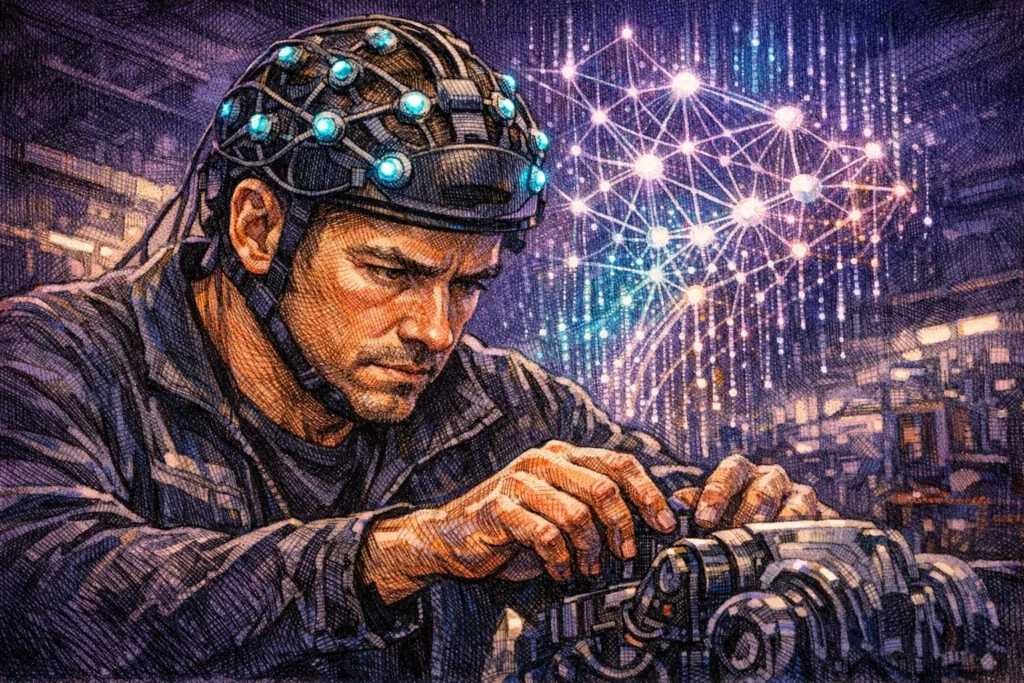
Encord2026-07-27 07:22:53Encord tests EEG-tagged robot training to capture human error signalsEncord, a California data tools startup, is testing whether EEG brainwave signals can fill a major gap in physical AI: the lack of high-quality training data. In a warehouse experiment in San Leandro, robot trainers known as “pilots” wear a camera-equipped helmet fitted with EEG sensors while performing tasks such as removing blocks from an unstable tower. The idea is to capture not only what happened, but also the operator’s cognitive state at the exact moment of hesitation, surprise, or error recognition. To do that, Encord is working with German neuroscience startup Zander Labs, whose EEG system is designed to infer states including error perception, execution intent, and surprise response. Encord’s robotics learning lead Vineeth Velmurugan said the industry’s data shortage is so severe that matching generative AI’s success in robotics could require training data equal to roughly five times YouTube’s full video library. The company is now building an initial EEG-labeled dataset to test whether those signals can improve customer robot models before deciding on a broader rollout. Encord also plans to recruit 10 more pilots this year, though questions around sensor cost, comfort, and signal stability in noisy warehouse settings remain unresolved.2160
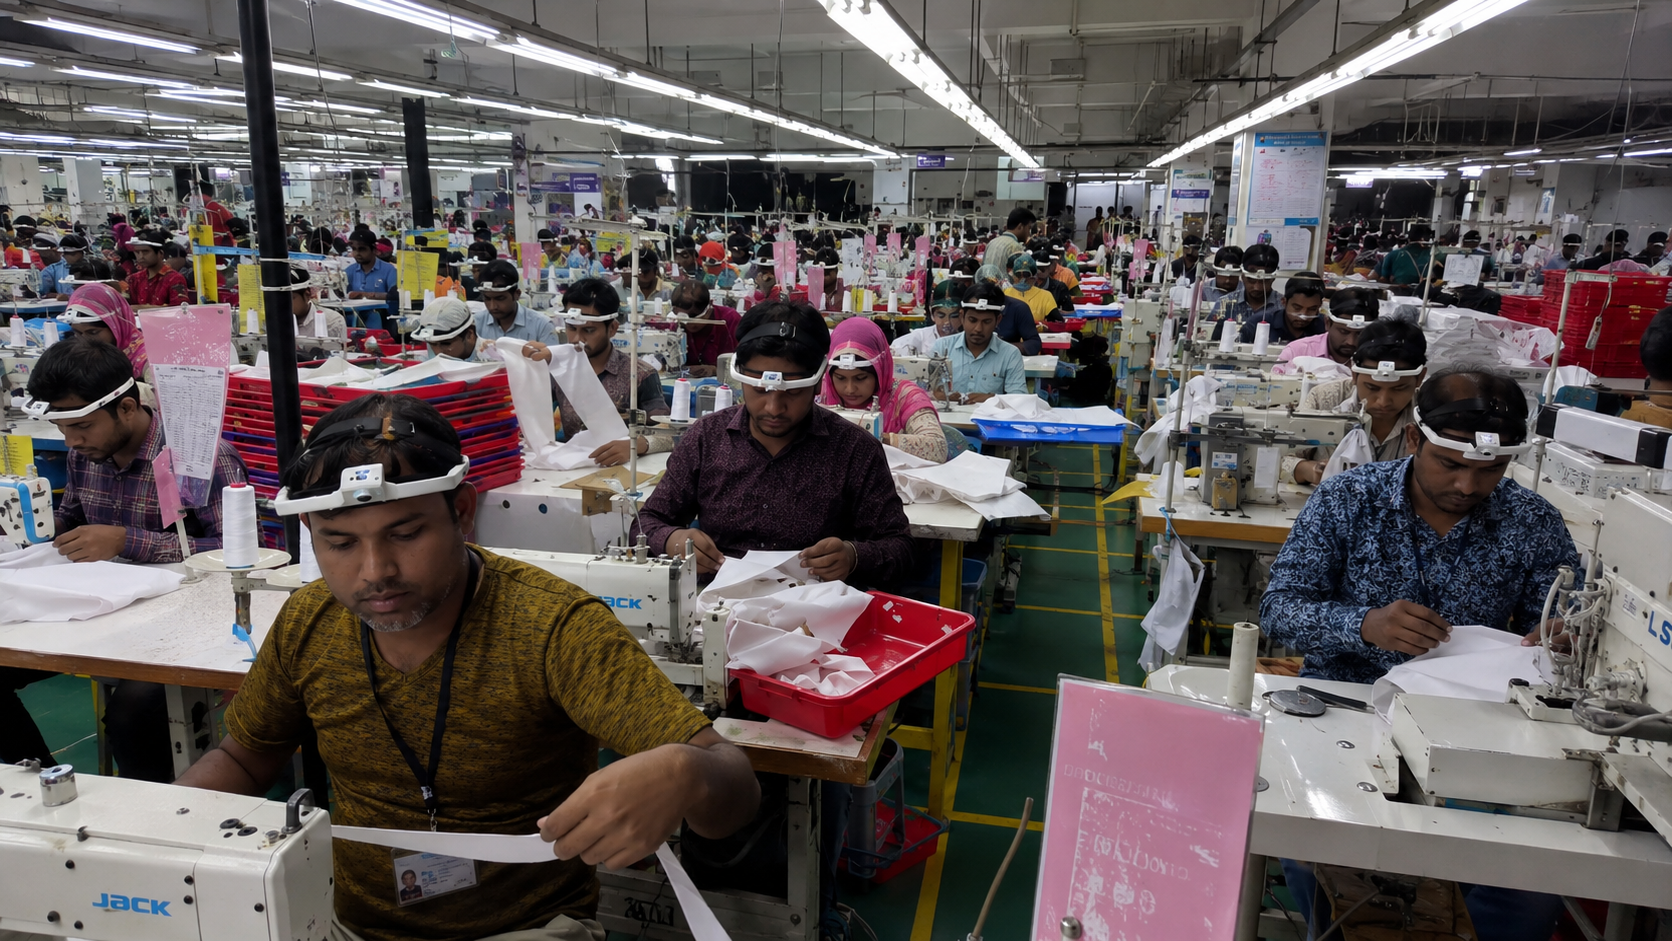
humanoid robo2026-07-23 03:05:14Tied iPhones on Foreheads: The Gig Workers Feeding Humanoid Robots at $15/HourWorkers in Nigeria and India strap iPhones to their heads to film household chores, earning $15/hour to provide real-world training data for humanoid robot companies like Tesla and Figure AI. Beneath the surface lurk privacy, data quality, and structural wage arbitrage issues.460
WAIC 20262026-07-17 08:59:20WAIC 2026 panel says embodied AI must clear narrow use cases first as competition shifts to data and closed-loop validationSpeakers at a WAIC 2026 roundtable said general-purpose embodied intelligence remains a distant goal, with near-term progress more likely to come from specialized deployments. Fudan University Vice President Jiang Yugang, AgiBot partner Yao Maoqing, Tashi Zhihang CEO Chen Yilun and Liangyuan Xinchuang CEO Jiang Xu discussed world models, arguing that their core task is to understand how the physical world works and predict the next state or action rather than simply render images. The panel identified data as the main bottleneck. Chen said existing video datasets lack key modalities such as force and touch, while ideal training data would need complete modalities, high-frequency interaction and real-world origins. Yao estimated that building common-sense physical prediction could require more than 100 million hours of real-world data. On commercialization, the speakers pointed to manufacturing as the clearest large-scale application over the next three years, though Jiang Xu said capability jumps may first appear in everyday settings such as homes and offices. The shared conclusion: the field’s next battleground is shifting from model architecture to access to high-quality data and the ability to validate systems through closed-loop scenarios.1860